 Stark
Local Models via Ollama
Run open-weight LLMs directly on your hardware.
1. Plain-Language Definition
Ollama is a powerful, open-source inference engine that runs Large Language Models (like Llama 3 or Qwen) directly on your local CPU or GPU. It serves as the 'brain' of StarkLLM.
2. Why It Exists
Running models locally is a highly effective way to maintain strong data privacy. It avoids subscription fees, is designed to work completely offline once downloaded, and allows you to swap models instantly.
3. What Breaks Without It
If you rely on OpenAI or Anthropic APIs, you must trust them with your highly sensitive data. Furthermore, if you lose your internet connection, your AI assistant stops working.
4. How StarkLLM Implements It
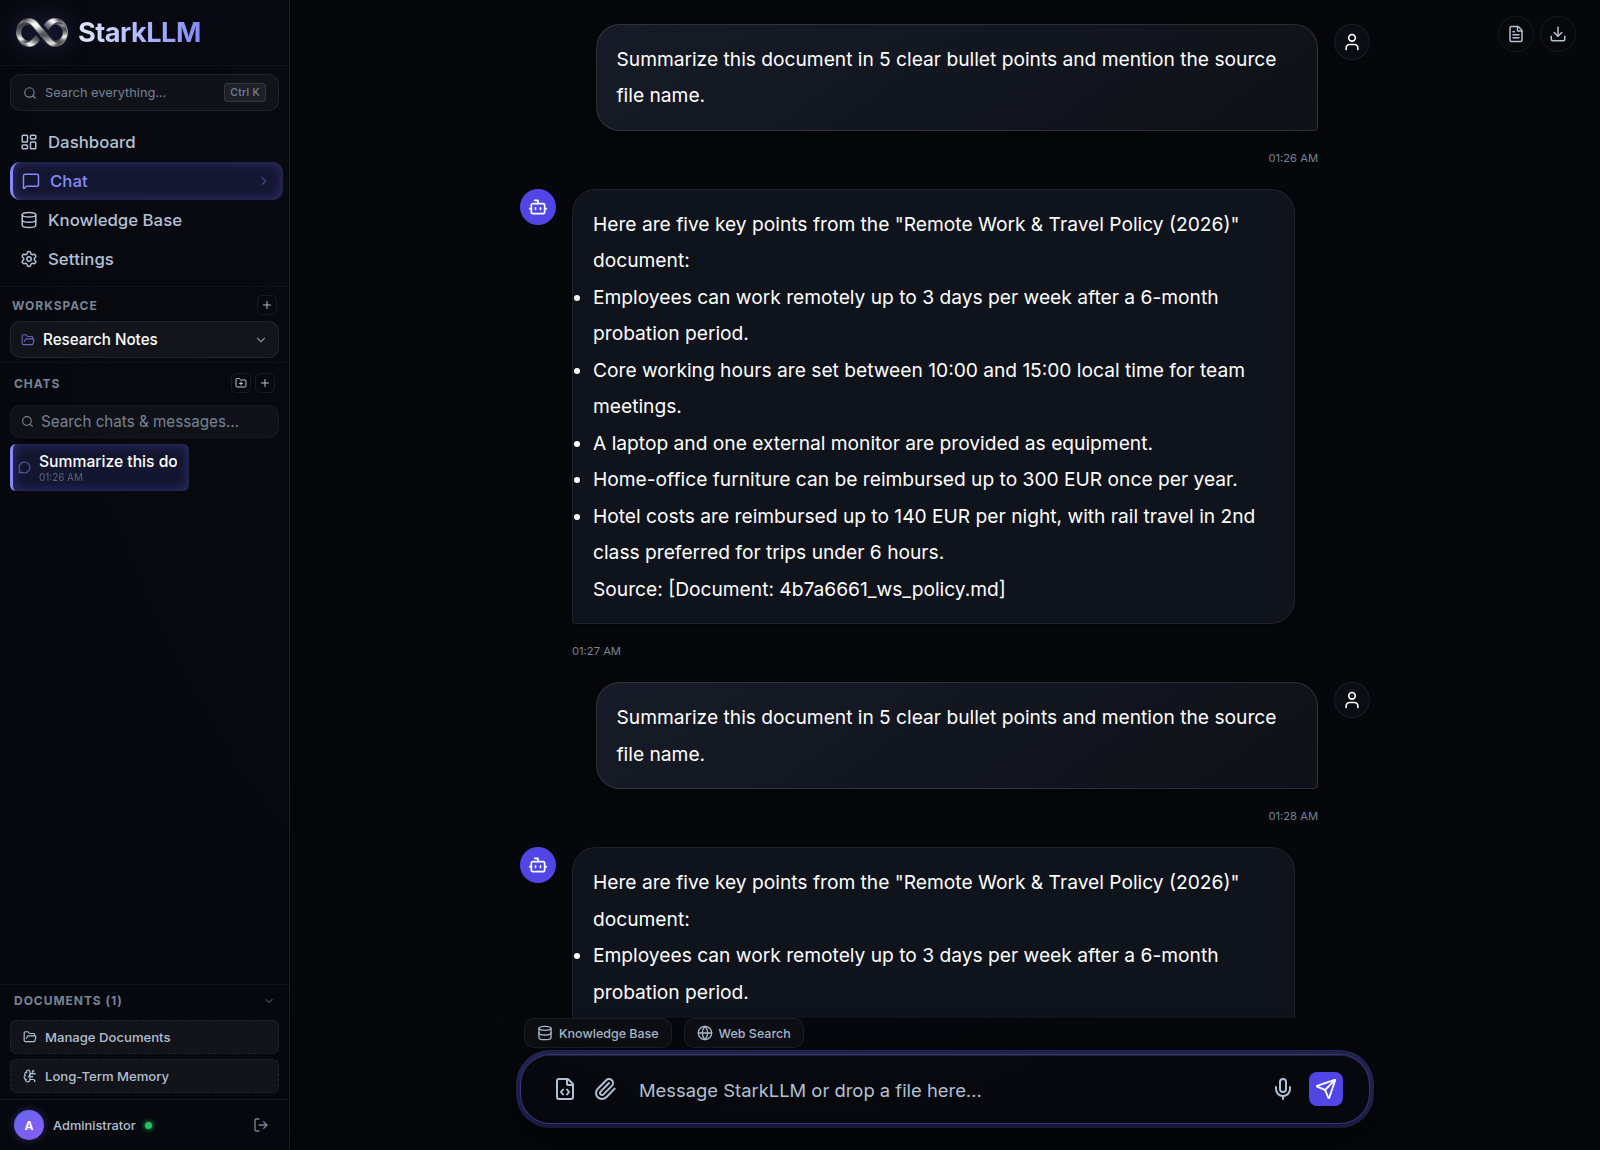
StarkLLM connects to the Ollama API running on `localhost`. When you send a prompt, StarkLLM retrieves document context, formats it, sends it to Ollama, and streams the response back to your UI.
5. User-Visible Benefit
Fast, deeply private, and free AI inference that scales with your hardware and never tracks your behavior.
6. Practical Example
You are on an airplane with no Wi-Fi. You can still upload a PDF to StarkLLM and have a full, intelligent conversation about it using a locally running 8B model.